FLEXPERTO — SPEECH-TO-TEXT / FINANCE & INSURANCE — 2022–2025
I took speech-to-text from MVP to production
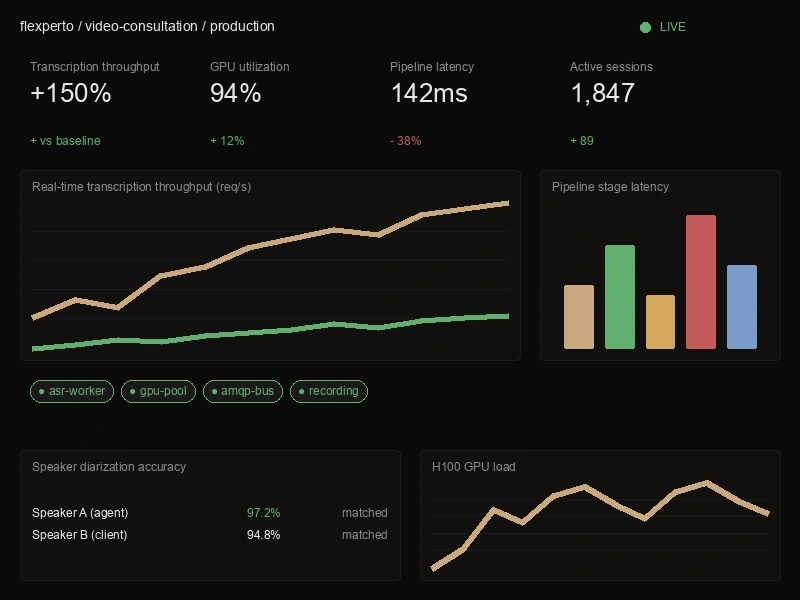
I started an internal speech-to-text MVP and owned its processing architecture through production at Flexperto. I designed the path from WebRTC audio capture through Silero voice activity detection and RabbitMQ to batched faster-whisper transcription on NVIDIA H100 hardware.
I used short audio segments and batching to increase transcription throughput. I compared word error rate on a 50-minute recording and observed the same WER as the baseline. The production pipeline processed batches; live transcription was a separate demonstration.
I also worked with local models and vector retrieval for meeting transcripts. For the wider platform, I designed OpenAPI interfaces and used UML data flows to trace service-level failures, including a lost-wakeup in expert-call routing.
WEBRTC · SILERO VAD · RABBITMQ · FASTER-WHISPER · NVIDIA H100